Desktop AI Supercomputing: Power Large Models Directly at Your Desk
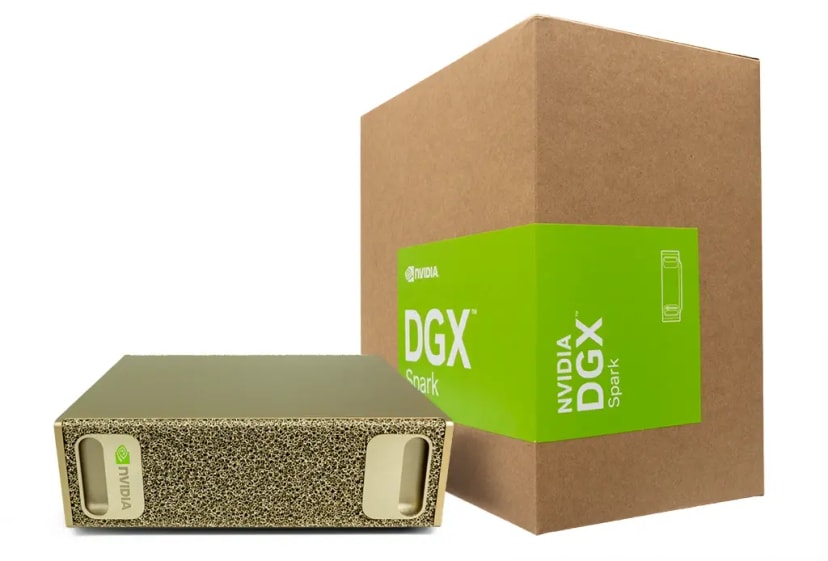
The NVIDIA DGX Spark is a breakthrough deskside AI supercomputer engineered to empower developers, enterprise AI researchers, and data science professionals with data-center-grade compute in a silent, ultra-compact form factor. Powered by the groundbreaking NVIDIA GB10 Grace Blackwell Superchip, the DGX Spark eliminates cloud latency, API rate limits, and data privacy vulnerabilities by running and fine-tuning frontier Large Language Models (LLMs) and autonomous AI agent pipelines directly on local infrastructure.
Core Architecture & Performance Highlights
- GB10 Grace Blackwell Superchip: Integrates a high-throughput Blackwell architecture GPU featuring 5th-Generation Tensor Cores with a 20-core heterogeneous Arm processor (10× Cortex-X925 high-performance cores and 10× Cortex-A725 high-efficiency cores) to deliver up to 1 PFLOP of FP4 AI inference performance.
- 128 GB Coherent Unified LPDDR5x Memory: Massive memory pool operating across a 256-bit bus at 273 GB/s bandwidth. Coherent CPU-GPU memory allows smooth, uncompressed execution and fine-tuning of multi-billion parameter models (such as Llama 3, Mistral, and DeepSeek) up to 200B parameters on a single unit.
- High-Speed Scale-Out with ConnectX-7: Built-in NVIDIA ConnectX-7 networking enables dual-unit scale-out via a high-speed link (up to 200 Gbps), expanding unified system memory to 256 GB for running massive frontier models up to 405B parameters locally.
- Enterprise Storage & Data Security: Built with a 4 TB NVMe M.2 SSD supporting hardware self-encryption, providing lightning-fast weight caching, checkpointing, and secure dataset processing for sensitive intellectual property and regulated workloads.
Turnkey Software Stack: Out-of-the-Box Local AI
The DGX Spark arrives preloaded with NVIDIA DGX OS (Ubuntu-based LTS), pre-configured and optimized to run enterprise AI workflows with zero setup friction:
- Native GPU Drivers & Acceleration: Pre-installed with NVIDIA CUDA, cuDNN, TensorRT-LLM, and NCCL.
- Framework & Engine Support: Optimized out of the box for PyTorch, vLLM, Ollama, Hugging Face Transformers, and llama.cpp.
- Agentic & Enterprise Tooling: Native compatibility with NVIDIA NIM microservices, NVIDIA NeMo agent framework, and LangChain/LlamaIndex pipelines.
Technical Specifications
| Component / Spec | Specification Detail |
|---|---|
| Processor Architecture | NVIDIA GB10 Grace Blackwell Superchip (20-core Arm CPU + Blackwell GPU) |
| AI Compute Performance | Up to 1 PFLOP (FP4 AI Inference) |
| Unified System Memory | 128 GB Unified LPDDR5x (273 GB/s Bandwidth, 256-bit Bus) |
| Internal Storage | 4 TB PCIe NVMe M.2 Solid State Drive (Hardware Encrypted) |
| Clustering & Scale-Out | Integrated NVIDIA ConnectX-7 (Up to 200 Gbps DAC/QSFP Link) |
| Wired & Wireless Networking | 1× 10GbE RJ-45 LAN, Wi-Fi 7, Bluetooth 5.4 |
| I/O Ports & Display | 4× USB Type-C, 1× HDMI 2.1a |
| Form Factor & Dimensions | Compact Desktop Appliance | 150 × 150 × 50.5 mm (~1.13 L volume, 1.2 kg) |
| Power Supply & Acoustic Profile | External High-Efficiency Power Supply (~170W TDP) | Near-Silent Whisper Quiet Operation |
| Operating System | NVIDIA DGX OS (Ubuntu Linux LTS Base) |
Engineered For Modern AI Workloads
Whether you are developing multi-agent architectures, fine-tuning task-specific LLMs with LoRA/QLoRA, deploying local RAG (Retrieval-Augmented Generation) vector databases, or testing computer vision models on edge infrastructure, the DGX Spark delivers reproducible data-center precision directly to your development workbench.